ML ENGINES · Low-bit decode attention · arXiv + Under Review

FOSCAR Accelerating Decode Attention over 2- and 4-Bit KV Caches through Affine Folding

Donglin Zhuang1,2, Pragaash Ponnusamy1, Xiaoxia Wu1, Shuaiwen Leon Song2, Zhongzhu Zhou1,2

1 Together AI   2 University of Sydney

FOSCAR moves scale and offset out of per-value KV reconstruction. Hopper uses BF16 Tensor Core operands, and Blackwell can feed packed INT2 codes into FP4 Tensor Cores after remapping.

Decode pipeline · NVIDIA B200

How FOSCAR worksFOSCAR 的工作原理

16-second silent walkthrough16 秒无声演示 · MP4 · Full-size figure查看原图

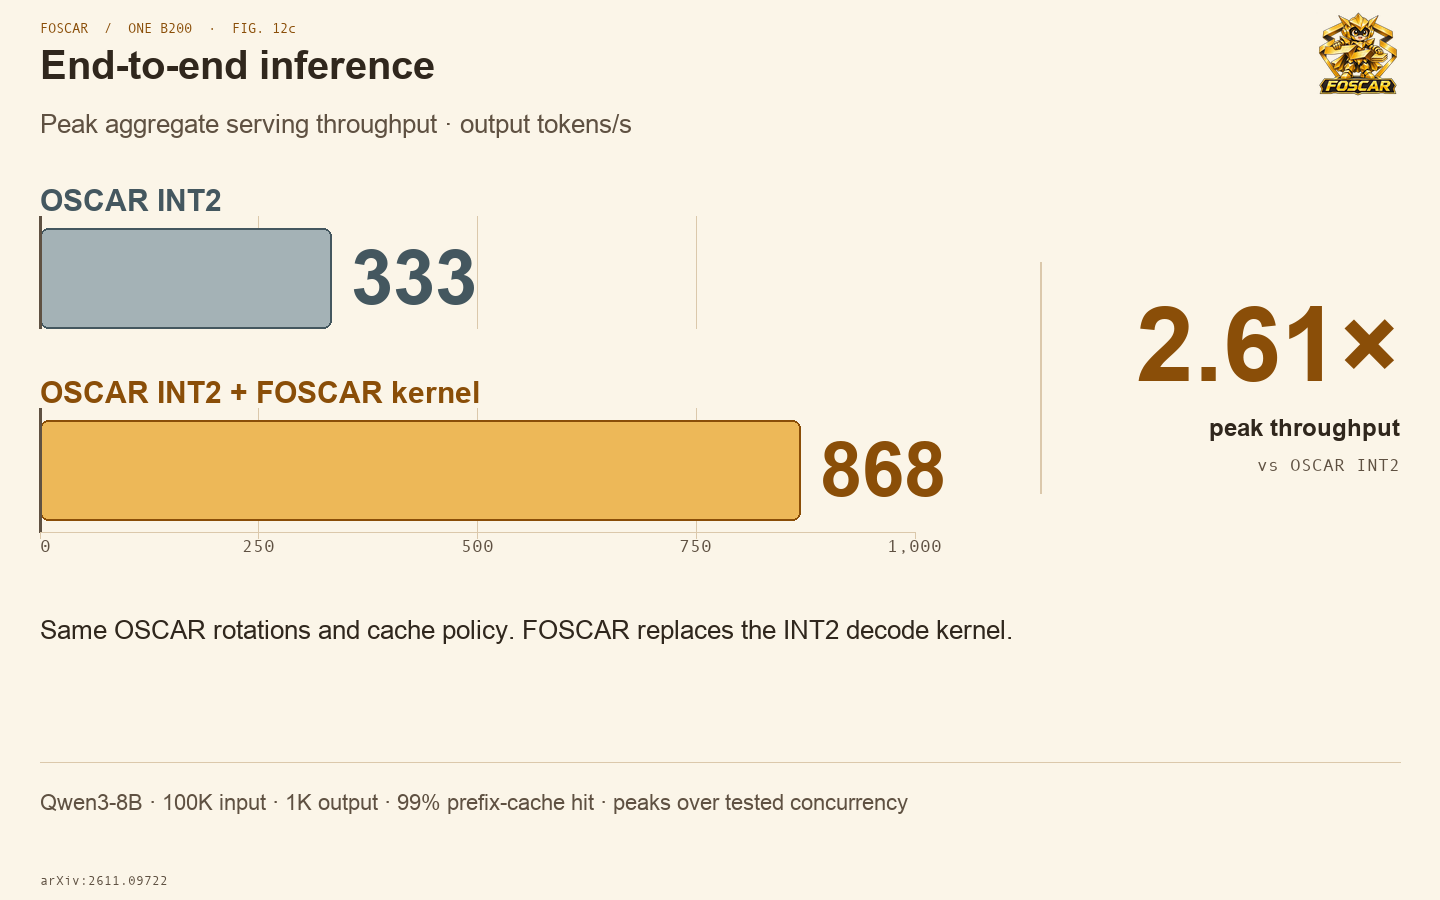
Peak serving throughput峰值服务吞吐量

2.61×
OSCAR INT2333
FOSCAR INT2868
Output tokens/s on one B200单张 B200 每秒输出 token 数 · Benchmark setup测试设置

Affine folding仿射折叠

Every decode step reads the KV cache. Packing it into 2 or 4 bits cuts memory traffic, but reconstructing each value still takes GPU instructions. FOSCAR builds Tensor Core operands from packed codes and applies each group's scale to a matrix input or partial result. The offset enters as an output correction.

每个解码步都要读取 KV 缓存。打包成 2 或 4 bit 可以减少内存流量,逐值重建仍会消耗 GPU 指令。FOSCAR 直接从打包编码构造 Tensor Core 操作数,把每组的缩放应用到矩阵乘法的输入或部分结果,并用偏移修正输出。

Where the scale lands缩放作用在哪里

Step 1/3 · Find the shared group and the reduction axis.第 1/3 步 · 找到共享分组与求和方向。

Scale the QK partial sum缩放 QK 部分和

One token’s scale is shared across the channels that QK sums over.QK 沿通道求和,同一个 token 的所有通道共享缩放。

D · channels通道 Σ QKᵀ reduces hereΣ QKᵀ 沿此求和
L · cached tokens缓存 token

Illustrative KV tile of quantized values q. Gold marks one group sharing a scale s and offset z.示意 KV 分块,q 为量化值。金色标出共享同一缩放 s 与偏移 z 的一组。

  1. Q other matrix input另一侧矩阵输入 × s · scale before multiply乘法前缩放
  2. Q · Kᵀ matrix product on code-derived operands对编码构造出的操作数做矩阵乘
  3. Group-local partial result组内部分和 × s · scale after multiply乘法后缩放
  4. + Σ(z · Q) offset correction before softmaxsoftmax 前加上偏移修正
  5. softmax corrected result continues修正后的结果继续计算
Scaled product缩放后的乘积 sl · Σd Qd ql,d
+
Offset correction偏移修正 zl · Σd Qd
Interactive adaptation of Figure 4.根据论文图 4 改编。
Try the arithmetic on four keys用四个键看折叠怎么算

Use query Q = [1, 2, 1, 1], INT2 codes q = [0, 1, 2, 3], scale s = 0.5 and offset z = −1. Reconstructing the keys gives [−1, −0.5, 0, 0.5]. Its dot product with Q is −1.5.

设查询 Q = [1, 2, 1, 1]、INT2 编码 q = [0, 1, 2, 3]、缩放 s = 0.5、偏移 z = −1。先重建得到键 [−1, −0.5, 0, 0.5],与 Q 的点积为 −1.5。

s · dot(Q, q) + z · sum(Q) = 0.5 × 7 − 5 = −1.5

The folded route gets the same result in exact arithmetic. It applies scale and offset once to this group's contributions.

在精确算术下,折叠路径得到同一个结果。缩放和偏移作用在这一组对结果的贡献上。
From packed bits to Tensor Cores从打包位到 Tensor Cores

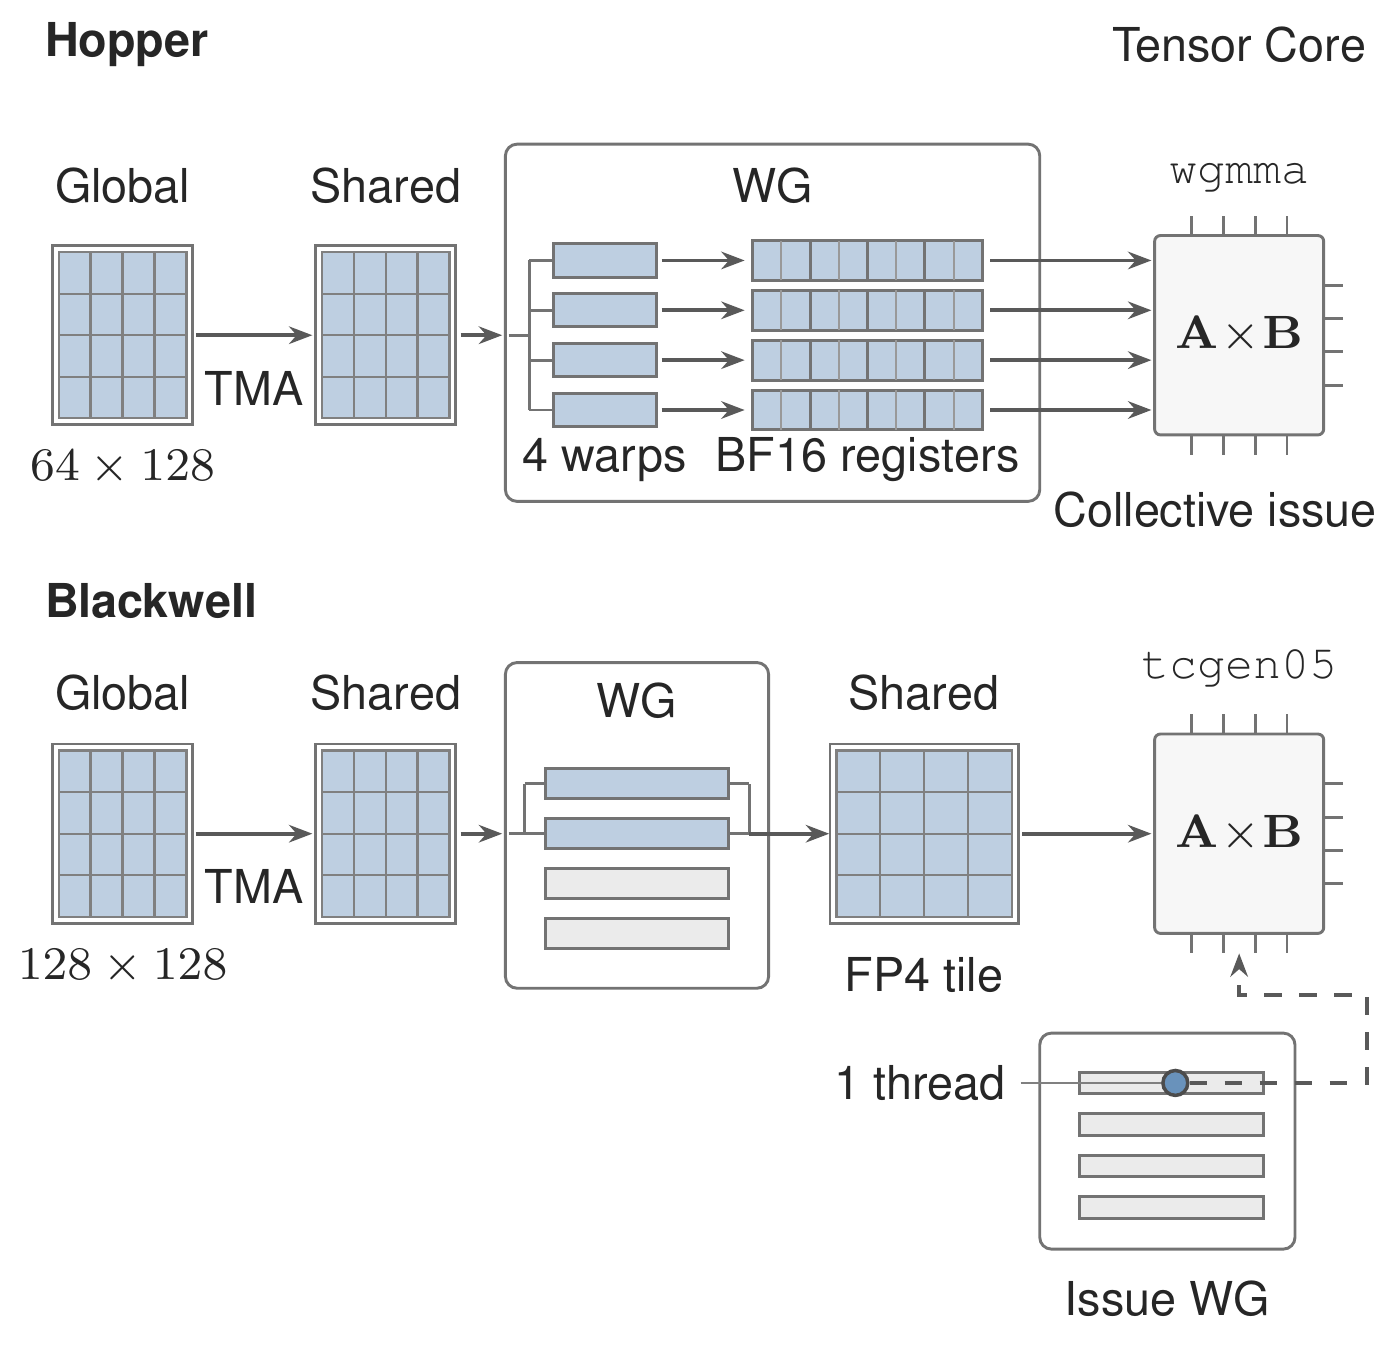
TMA moves packed tiles into shared memory. On Hopper, consumer warpgroups construct BF16 operands and accumulate in registers. On Blackwell, the INT2 path zero-extends codes into FP4 operands in shared memory, and the matrix products accumulate in tensor memory (TMEM).

TMA 把打包分块搬到共享内存。Hopper 的消费者 warpgroup 构造 BF16 操作数并在寄存器中累加。Blackwell 的 INT2 路径通过补零构造 FP4 操作数,放入共享内存,矩阵乘积累加到张量内存(TMEM)。

Follow one KV tile跟踪一个 KV 分块

WG0 · producer生产者

TMA copies the packed KV tile. For channel-wise K, WG0 also prepares scaled Q.TMA 搬运打包的 KV 分块。若 K 按通道分组,WG0 还负责准备缩放后的 Q。 HBM → SMEM

Copies later tiles ahead.提前搬运后续分块。

WG1 / WG2 · consumers消费者

The two consumers alternate even and odd tiles; one takes this tile.两个消费者交替处理奇偶分块,其中一个接手本块。

Builds BF16 operands from packed bits in registers and issues wgmma for QKᵀ.在寄存器中由打包比特构造 BF16 操作数,并发出 wgmma 计算 QKᵀ。 BF16 · REG

QK correction → online softmax → PV → V correction → output, all in registers. At the end, one consumer merges both partial outputs.QK 修正 → 在线 softmax → PV → V 修正 → 输出,全程在寄存器中完成。最后由一个消费者合并两路部分结果。 REG

Tensor Cores

wgmma accumulates QKᵀ in the issuing warpgroup's registers.wgmma 把 QKᵀ 累加到发出指令的 warpgroup 的寄存器中。 REG

PV accumulates in the same consumer's registers.PV 同样累加在该消费者的寄存器中。 REG

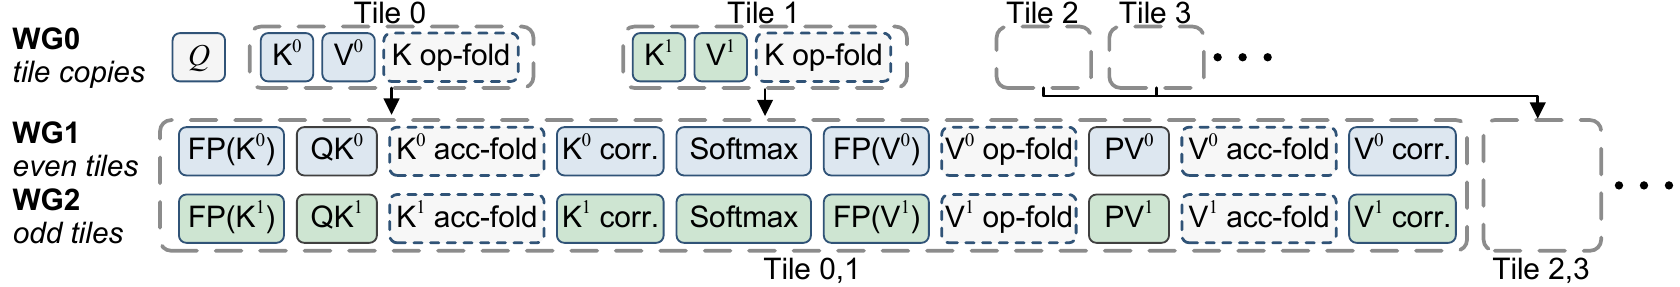
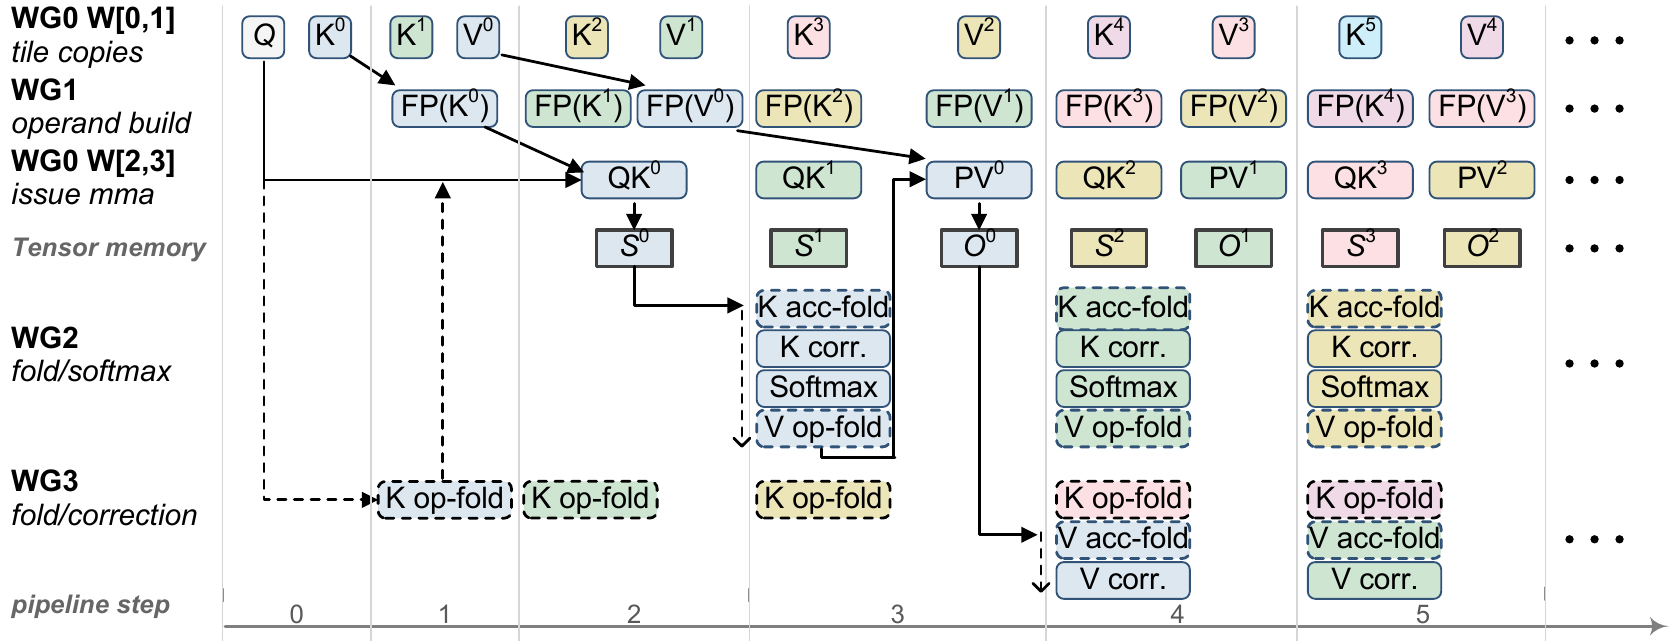
Interactive adaptation of Figure 7. Stages show the dependencies for one tile. The original schedules below show how tiles overlap.论文图 7 的交互式改编。各阶段展示单个分块的依赖关系。下方原图展示不同分块如何重叠执行。
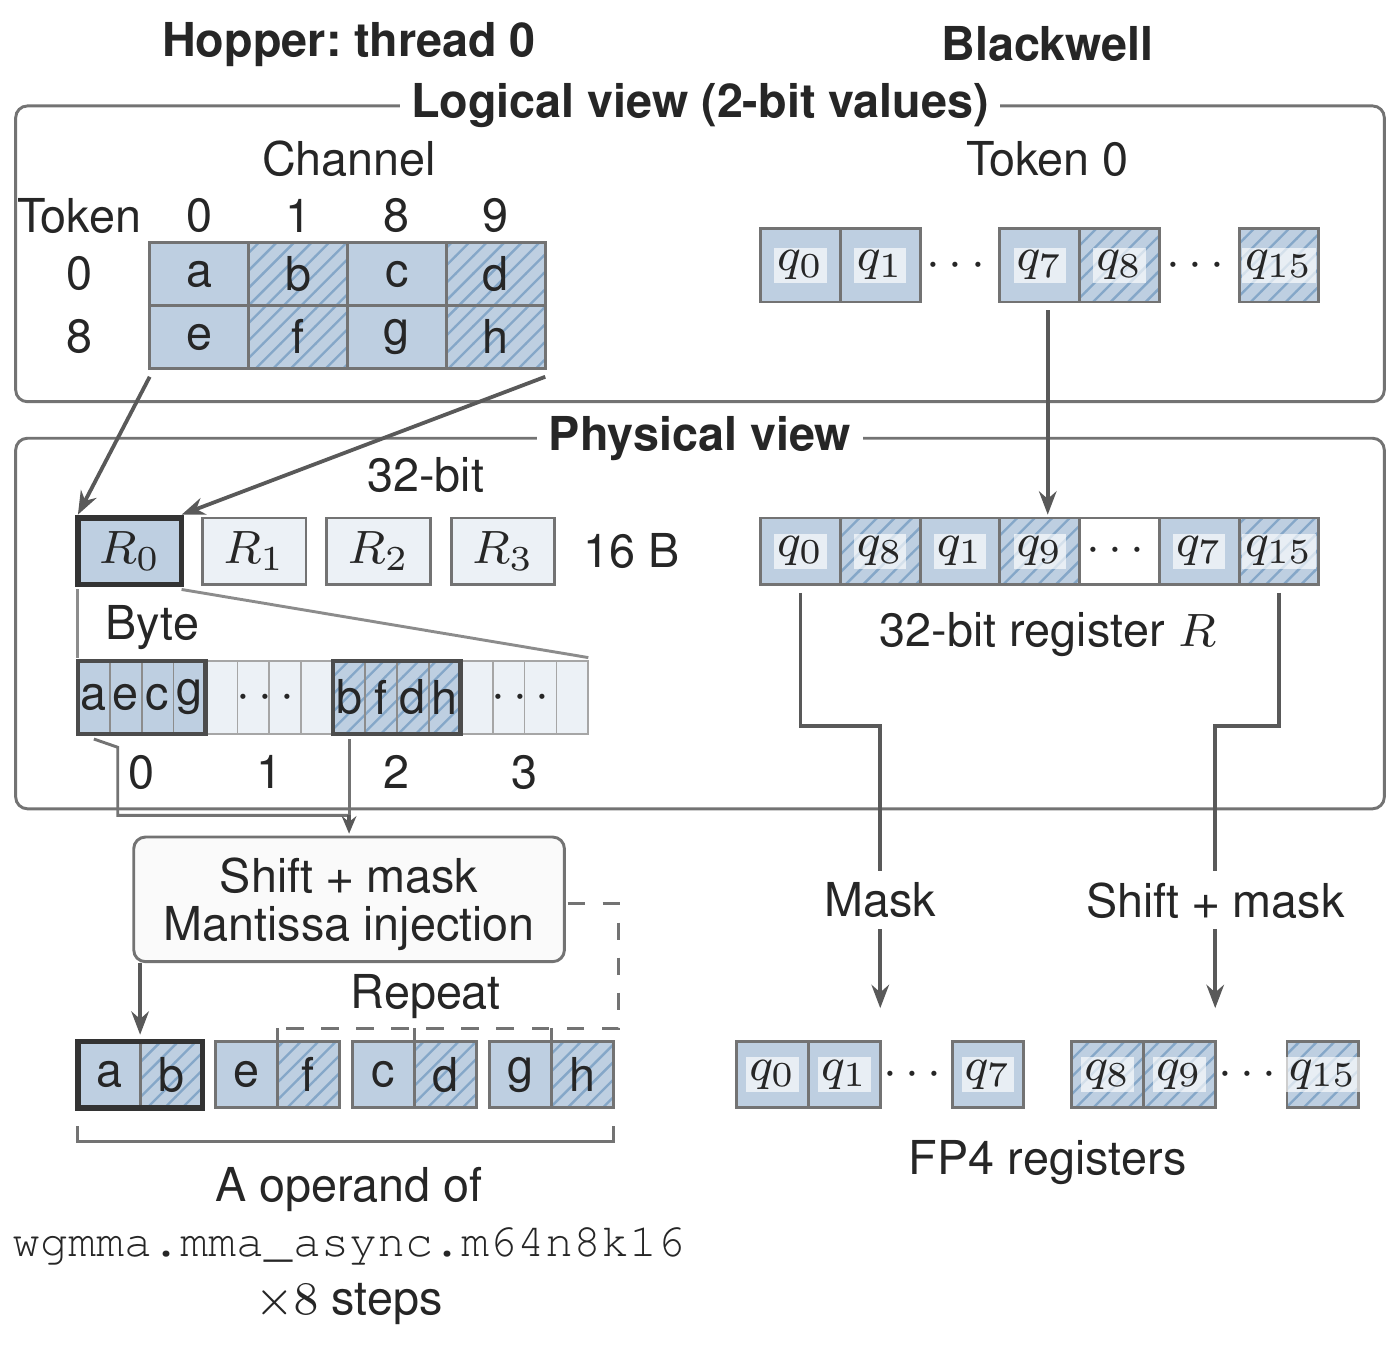
Original register packing and dataflow figures查看原始寄存器打包与数据流图
INT2 bit packing and operand construction in Hopper and Blackwell registers
Figure 6a · Register packing and bit-level operand construction图 6a · 寄存器打包与操作数位构造
INT2 K dataflow from global memory to Tensor Cores through BF16 registers on Hopper and an FP4 shared-memory tile on Blackwell
Figure 6b · How an INT2 K tile reaches the Tensor Cores图 6b · INT2 K 分块如何到达 Tensor Cores
Original H100 and B200 pipeline schedules查看 H100 和 B200 原始流水线调度图
H100 schedule with one TMA producer and two consumer warpgroups alternating tiles
Figure 7a · H100, alternating consumer warpgroups图 7a · H100 的两个消费者 warpgroup 交替处理分块
B200 schedule with TMA and MMA issue in WG0, operand preparation in WG1, TMEM, and corrections and softmax in WG2 and WG3
Figure 7b · B200, separate issue, operand preparation, and correction lanes图 7b · B200 分别调度指令发射、操作数准备与修正

Decode kernel speedup解码内核加速

Geometric mean latency speedup over FlashInfer BF16 on each GPU. Bars share a 0–4× scale.

在各自 GPU 上与 FlashInfer BF16 比较,取延迟加速比的几何平均值。横条使用同一 0–4× 刻度。

NVIDIA H100

INT23.36×
INT42.83×

NVIDIA B200

INT22.67×
INT42.30×

Serving with SGLangSGLang 端到端服务

Replace OSCAR's INT2 decode kernel with FOSCAR while keeping its rotations and BF16 sink and recent windows. The benchmark uses Qwen3-8B, 100K input tokens, 1K output tokens, and a 99% prefix-cache hit rate. Values are peak aggregate output tokens/s across tested concurrency levels.

将 OSCAR 的 INT2 解码内核换成 FOSCAR,沿用 OSCAR 的旋转和 BF16 起始与近期窗口。测试使用 Qwen3-8B、100K 输入、1K 输出和 99% 前缀缓存命中率。表中为各并发设置下测得的峰值总输出 token/s。

GPUOSCAR INT2With FOSCAR换用 FOSCARGain倍数
H1002694871.81×
B2003338682.61×
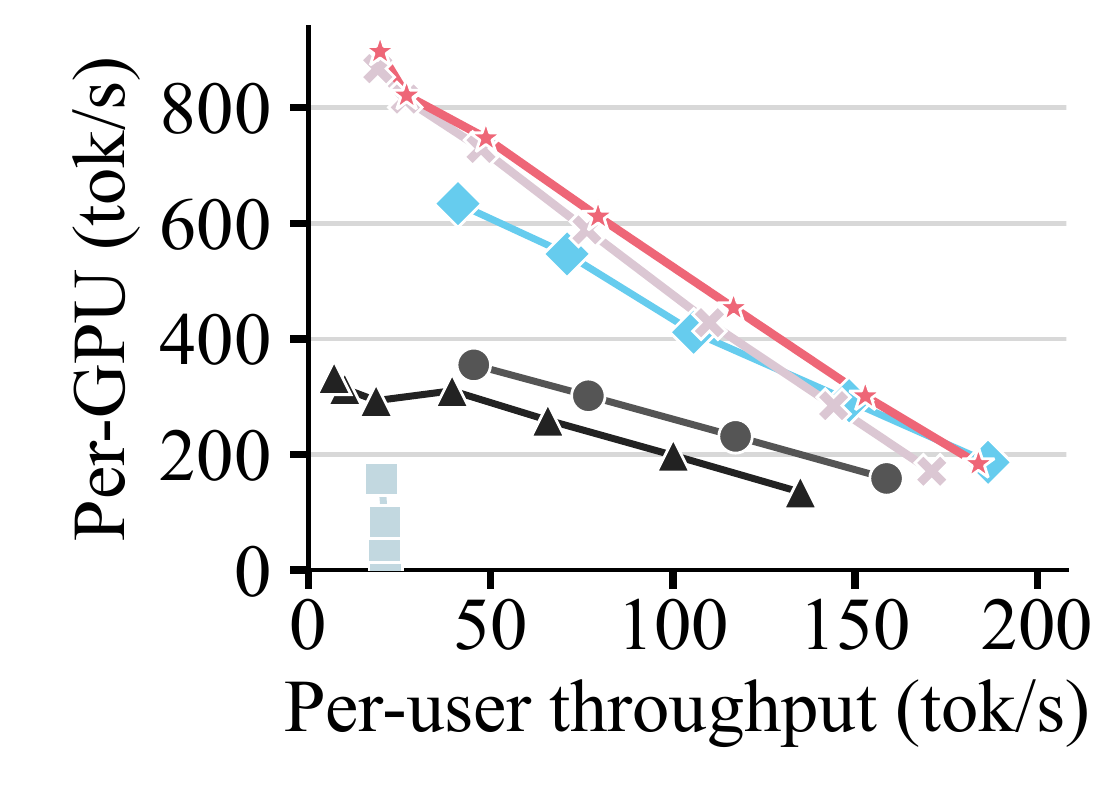
See the B200 throughput trade-off查看 B200 的单用户与总吞吐对比
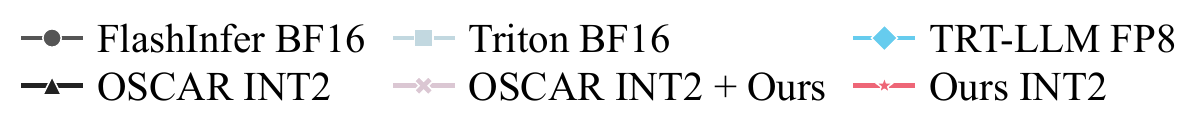
Legend for FlashInfer BF16, Triton BF16, TRT-LLM FP8, OSCAR INT2, OSCAR INT2 plus FOSCAR, and FOSCAR INT2 Original B200 plot of per-user throughput on the horizontal axis and aggregate per-GPU throughput on the vertical axis, at 99% prefix-cache hits
Figure 12c · Each point is one tested concurrency setting. Higher on the vertical axis means more total output tokens per second.图 12c · 每个点对应一个测试并发设置。纵轴越高,每秒输出的 token 总数越多。

Original figures from the FOSCAR paper (arXiv:2611.09722, CC BY 4.0).原图来自 FOSCAR 论文(arXiv:2611.09722,CC BY 4.0)。